
Undefined
We Keep Asking Whether Human Performance Works. We Haven’t Decided What “Working” Means.
You can’t solve a problem that was never defined.
As with most programs in the government, embedded human performance is under increasing pressure to demonstrate its value. Leaders want metrics. They want return on investment. They want evidence that these expensive programs are improving readiness, increasing lethality, reducing injuries, and producing healthier, more capable service members.
Admittedly, these are totally reasonable requests. In fact, to expect that the folks funding these types of programs wouldn’t be interested in outcomes would be absurdly naïve.
But the longer I’ve spent in this space, the more convinced I’ve become that our problem isn’t measurement. It’s that we never actually defined what we were trying to solve in the first place.
So again I say: you can’t solve a problem that was never defined. If you’ll bear with me, we can actually unpack a debate amongst 20th-century philosophers of science to help explain why. Hold on tight.
This is so on-brand for MOPs and MOEs…
Popper and the Appeal of Falsification
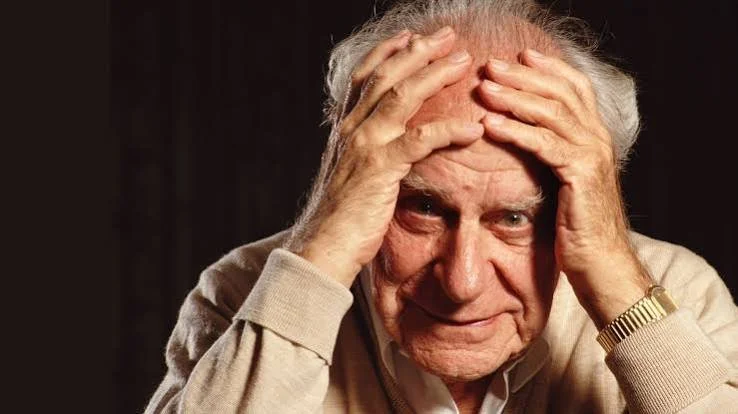
Meet Karl Popper. Born in Austria in 1902, Karl Popper was an academic, social commentator, and one of the 20th century’s most influential philosophers of science.
His primary theory revolved around this idea of falsifiability; namely, that the way to distinguish between science and non-science is that scientific theories must be able to be proven false through testing. Zooming out, we don’t prove a theory true by accumulating observations that support it…we make predictions and expose those predictions to the possibility of being wrong.
A simple framework would look something like this:
Theory → Prediction → Test → Falsification
If I make a claim that an intervention reduces MSK injuries by 20%, I should be able to test that claim. If injuries don’t decrease as a result of my intervention, then my hypothesis has a problem. Inarguably, there is something very appealing about this framework. Make a claim, measure it, see if it worked.
The problem is, science rarely works this cleanly.
Take a strength and conditioning example. Let’s say we implement an intervention and it fails to improve physical performance. What actually failed? Was it the training program? Was adherence poor? Was the program itself too short? Too long? Was nutrition adequate? Did we choose the wrong outcome measure?
The truth is, a failed prediction rarely tests a single idea in isolation. It tests an entire collection of assumptions surrounding that idea. Scientists therefore don’t (and shouldn’t) discard the entirety of an otherwise useful theory every time they encounter contradictory evidence.
Good effort, Popper.
Kuhn and The Paradigm
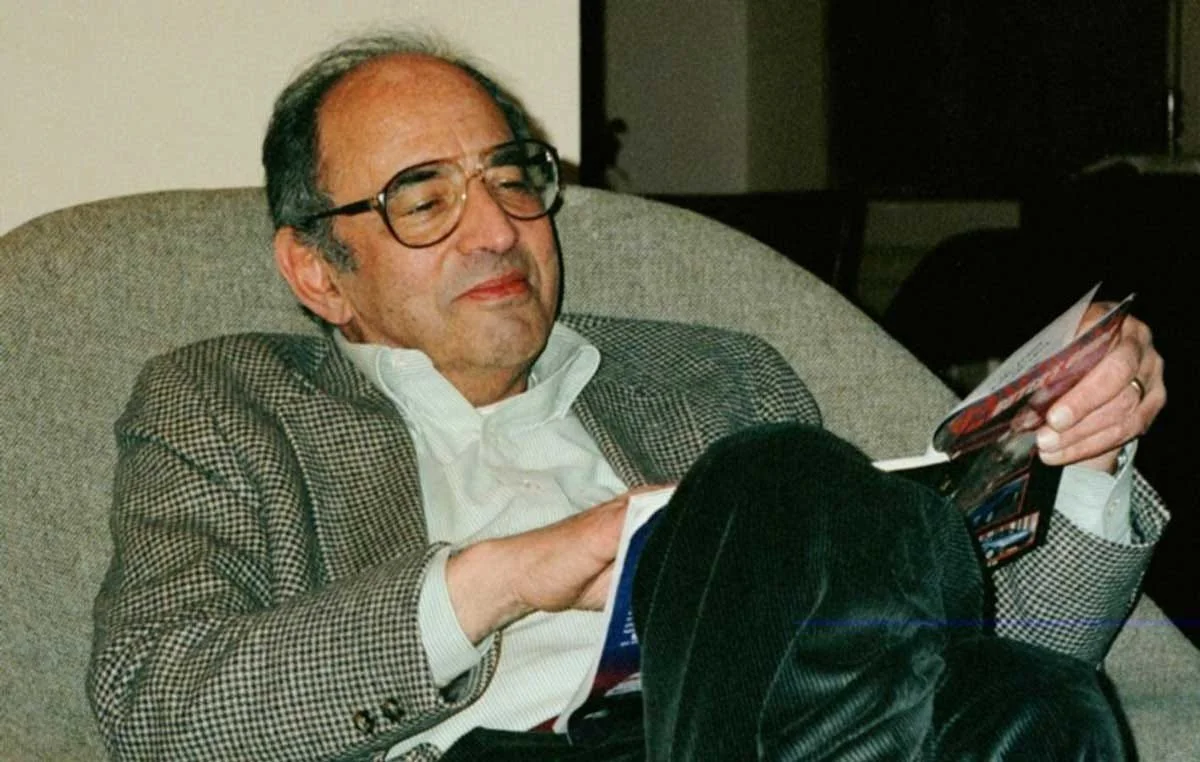
Allow me to introduce our next scientific philosopher, friend of the show, Thomas Kuhn.
Born in 1922, Thomas Kuhn, like Karl Popper, was a monumental philosopher of science. His 1962 book “The Structure of Scientific Revolutions” was massively influential in both the niche field of the philosophy of science as well as the broader cultural zeitgeist. I talk about this book all the time. If you’ve ever uttered the phrase “paradigm shift,” it’s because of Thomas Kuhn (he invented it).
Which brings us to his argument against Popper’s falsifiability theory. Scientists, Kuhn argued, generally operate within larger conceptual frameworks called paradigms.
A paradigm more or less determines what questions scientists ask, what methods they use, what counts as evidence, and even what problems are worth solving in the first place. Newtonian Mechanics, for example, would constitute a paradigm.
When you think about it, most scientific work isn’t actually revolutionary. Kuhn calls this “normal science,” or the work most scientists spend most of their time doing: solving puzzles within an existing paradigm.
Over time, however, anomalies start to accumulate. Investigation exposes gaps. Things stop “fitting.” At some point, the existing paradigm no longer adequately explains the world around us, and it’s at this point that conditions are set for a scientific revolution and, potentially, a paradigm shift.
Newtonian Mechanics gives way to Relativity and Quantum Mechanics. Miasma (bad air) gets replaced by Germ Theory. Geocentrism is abandoned in favor of Heliocentrism. Periodization falls apart in the face of the MOPs and MOEs Emergent Programming Revolution (lol…).
This is a much more realistic description of scientific progress than simply sticking with Popper and saying “this idea failed, throw it away.” But that doesn’t mean Kuhn is bulletproof. If scientists operate within competing paradigms, how do we rationally determine which one is making progress in real time? Or are we only ever able to really identify paradigms after the fact?
Lakatos and Scientific Research Programmes
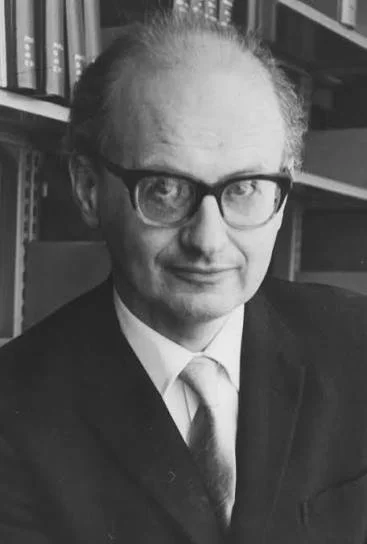
Please welcome the third cog in our wheel, Imre Lakatos. I was first exposed to Lakatos’ work after our episode with Franco Impellizzeri. Upon learning more about his approach, all of these pieces fell into place. Let’s discuss.
Lakatos, like Kuhn, was born in 1922 (good year for science, apparently). A philosopher and mathematician, his major contribution to the philosophy of science was his model of the “research programme.” This concept was, quite literally, formulated in an attempt to resolve the conflict between Popper’s falsification and Kuhn’s paradigm shifts.
From a 10,000ft view, the idea is that instead of evaluating individual hypotheses, we should evaluate scientific research programmes over time.
A research programme is based on a “hard core” of foundational assumptions surrounded by what he calls a protective belt of auxiliary hypotheses. The hard core isn’t abandoned every time contradictory evidence appears; rather, scientists engage in research to modify the protective belt…which is effectively expendable.
Let’s make this make sense. Consider resistance training.
A foundational, hard core assumption might be: resistance training produces physiological adaptations that increase strength. Around that core sits a massive protective belt of additional assumptions: volume matters, intensity matters, frequency matters, exercise selection matters, etc. If one study finds that a particular resistance training program doesn’t increase strength, we don’t immediately conclude that resistance training doesn’t work. We examine the assumptions surrounding the intervention. Science progresses through this sort of investigative rigor.
BUT…
Lakatos recognized an important danger, and here is where we start to make our way back towards embedded human performance in the military.
Research programmes can become either progressive or degenerating.
A progressive programme encounters problems, modifies its theories, generates new predictions, and successfully predicts new findings. It evolves with change.
A degenerating programme, on the other hand, evolves in a different direction. Each failure produces another explanation for why the original theory wasn’t really wrong in the first place. The protective belt grows increasingly elaborate, but the programme itself produces little genuinely new knowledge. It’s a subtle distinction, but an important one.
Progressive Programme:
Problem → Revised theory → new prediction → successful test
Degenerating Programme:
Problem → Revised explanation for why the failure doesn’t count → another failure → another explanation → another failure…
The issue isn’t that we encounter failures or contradictory evidence. All good research inevitably encounters failures or contradictory evidence. The question is whether those contradictions actually end up leading us anywhere.
So, What Problem is Embedded Human Performance Actually Trying to Solve?
Whew. We made it. Back to something we understand. Or do we?
Let’s consider the Army’s H2F system. If we ask what H2F is intended to accomplish, we tend to get familiar answers:
Increase Readiness
Improve Lethality
Build Resilience
Optimize Human Performance
These all sound reasonable, but they don’t actually say anything. They’re definitely not problem statements. In all actuality, they’re nothing more than aspirations.
Take “readiness,” for example. What does it actually mean for H2F to “increase readiness”? Fewer non-deployable soldiers? Fewer injuries? Fewer profiles? Better fitness? All of the above? None of the above? Each of these could reasonably be described as readiness, but they’re not the same problem. They each have different causes, require different interventions, and should definitely be evaluated using different outcomes.
Let’s get wild here and take a look at “Lethality,” because that one is even worse!
What does it mean for a dietitian to increase lethality? Or a strength coach? Or a chaplain? How about an occupational therapist? Sure, improved nutrition, higher PT scores, better sleep, etc. might all contribute to battlefield effectiveness, but let’s be real with ourselves…there are several causal steps between improving a deadlift and increasing the lethality of a soldier.
Simply demanding that an H2F team “prove its contribution to lethality” skips over the most important intellectual work:
What is the causal pathway we’re proposing in the first place??
Measurement Can’t Rescue an Undefined Construct
Most of my subheadings are meant to be cheeky. This one is meant to deliver a blow.
When a senior leader asks “how do we know H2F is improving readiness,” the embedded team responds with data. Utilization, appointments, classes, training sessions, injury rates, profiles, whatever the data point-du-jour is…and the dashboard continues to grow. But eventually, someone intelligent looks at the dashboard and asks, “Okay, but does any of this actually prove we’re increasing readiness?”
Inevitably, the answer isn’t satisfying. So what do we do?
Collect more metrics.
The problem is, as I said: measurement (and more measurement) cannot rescue an undefined construct.
We can, and often do, measure hundreds of variables with extraordinary precision, but we still have no idea whether we’ve accomplished our objective if nobody clearly articulated what that objective means in the first place. This creates a very dangerous feedback loop…a feedback loop that I fear we’re all already caught up in.
Leadership asks H2F to improve an ambiguous strategic outcome → H2F measures what it can reasonably observe → Those measurements fail to demonstrate the ambiguous strategic outcome to the satisfaction of said leader → Leadership demands better measures → H2F produces increasingly sophisticated (and expensive) dashboards…
See the issue? The original ambiguity remains untouched. The problem was never insufficient data…the problem existed before the first data point was collected. Hell, the problem existed before the first staff member was even hired.
Start with Actually Defining a Problem
What if, instead of telling an embedded performance team to “increase readiness,” we gave guidance like this:
“Our formation has an unacceptably high rate of preventable lower-extremity MSK injuries. These injuries are reducing training availability and creating a substantial population of soldiers on temporary profile.”
Oh man. NOW we have a problem. So, what comes next? The causal hypothesis:
“We believe inadequate physical preparation for occupational demands is a significant modifiable contributor to said problem.”
We’re cooking with gas now. Let’s take it a step further and propose an intervention:
“Implement progressive strength and conditioning programs into unit physical training.”
But wait. There’s more. We also need to attach a prediction to our proposal:
“Over the next 24 months, preventable lower-extremity injuries should decline while physical performance and training availability are maintained or improved.”
Holy shit. We’ve done it. We’ve created a Lakatosian research programme. If injuries decline, we learn something. If they don’t, we still learn something. Perhaps the intervention was wrong? Or maybe implementation was poor? Maybe our causal hypothesis was off? Maybe sleep or recovery are the more important variables? Perhaps leadership practices matter more than programming? Regardless of the questions we start to ask, we modify our protective belt, make another prediction, and test it.
The important point is that failure isn’t something to hide from. Failure produces information. The programme becomes progressive, not degenerative.
The Ugly Truth: The Problem May Be Further Upstream Than the Program
It’s important to peel back a few more layers, because thus far this could easily read as a bit of criticism towards H2F and embedded human performance at large. But I don’t think that’s actually where the most interesting criticism belongs.
Human performance teams generally do exactly what organizations tend to do when handed a poorly specific objective: interpret the objective locally, deliver services, measure available outputs, and attempt to demonstrate value afterwards. But the more fundamental problem is further upstream.
The military frequently asks human performance systems to demonstrate causal effects on vaguely defined strategic outcomes without first articulating:
What specific problem we’re trying to solve
What we believe actually causes that problem
Which part of that causal system human performance can reasonably influence
What interventions follow from that hypothesis
What outcomes we should change if we’re correct
Over what period should we expect the change
Only after we’ve answered those questions does measurement really become meaningful; otherwise, we’re asking programs to retroactively construct evidence for an aspiration.
Theory Before ROI
As we stated at the outset, it’s not incorrect for military leaders to demand evidence from human performance programs. That’s not the argument I’m trying to make. These programs use substantial resources, and it’s only natural that we’d ask whether or not these resources produce meaningful effects. Accountability, however, requires more than dashboards. Accountability requires intellectual clarity from the people defining the requirement.
Before we ask ourselves “what is the ROI of H2F,” we should be able to answer “what problem did we build H2F to solve?” Before asking whether H2F contributes to readiness, lethality, or whatever else, we should be able to articulate the causal chain connecting an intervention to those aforementioned outcomes.
Only when we’ve done that can Popper’s demand for falsifiability become useful. Only then can we identify Kuhnian anomalies worth investigating. And more importantly, only then can we use Lakatos’ framework to determine whether military human performance is becoming a progressive research programme – one that learns from failures, generates better predictions, and produces useful knowledge – or a degenerating one that continually constructs new explanations and metrics around assumptions it never adequately tested in the first place.
In closing, I don’t think military human performance has a measurement problem at all. I think it’s doing the best it can within a “problem-definition” problem.
And no dashboard, wearable, or intervention is going to solve that.